Tencent Unveils Hy-Nomas, an Interactive Generative AI Video Model
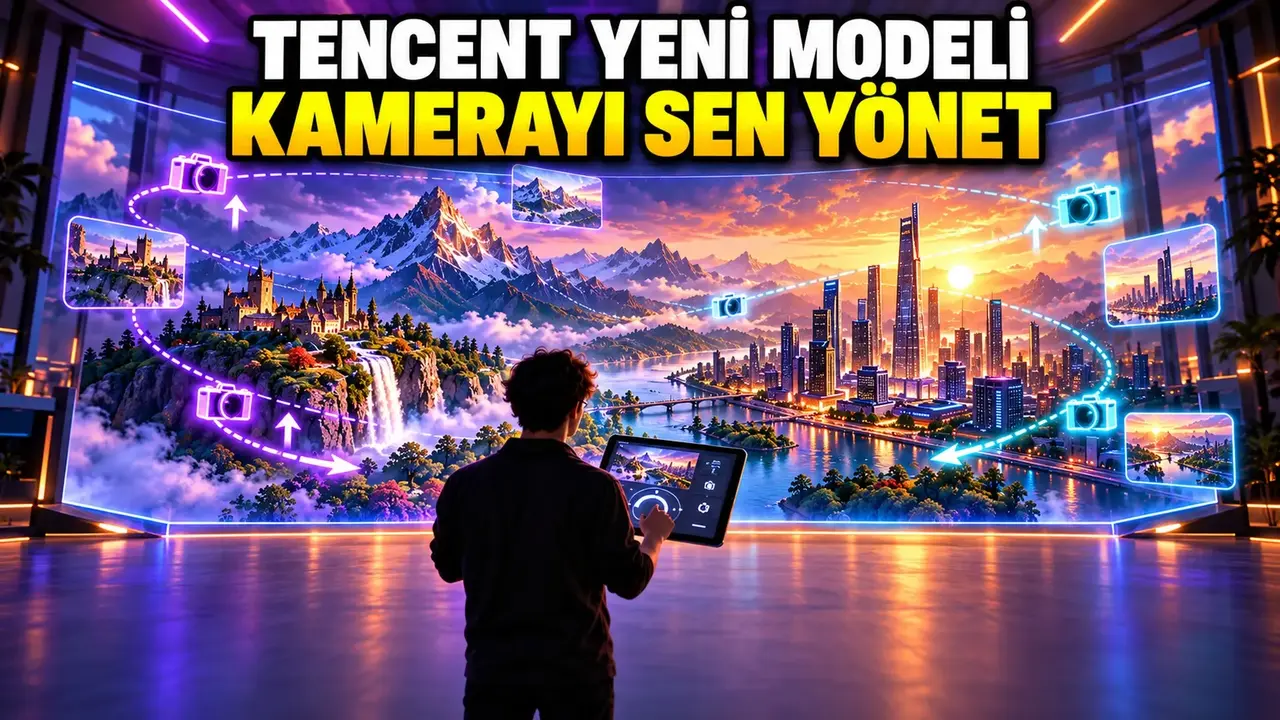
Tencent’s Hunyuan AI team has officially released Hy-Nomas, an innovative open-source video world model that allows users to guide generation through real-time text prompts and camera trajectory inputs. Announced in late October 2026, this technology distinguishes itself by generating videos in sequential segments rather than as a single, static file, enabling continuous user interaction throughout the process. By maintaining a world memory cache, the model ensures contextual consistency as users modify scene elements, adjust environmental styles, or command character movements on the fly. This breakthrough offers unprecedented control for creators looking to integrate interactive AI into their workflows.
- The Hy-Nomas model utilizes a segmented generation process that allows for real-time adjustments to video content via text and camera movement.
- Tencent has released the model under the Apache 2.0 license, providing full access to its code and weights on GitHub.
- The architecture supports efficient deployment on consumer-grade hardware, including the NVIDIA GeForce RTX 4090, through advanced quantization techniques.
The Model Manages Complex Sequential Generation
Hy-Nomas functions as a sophisticated video world model that supports multi-step interactions. According to the official documentation on Hugging Face, the system operates by storing previous frame data in a cache, which allows it to maintain the coherence of a persistent world even as users introduce new objects or change the atmospheric conditions of the video. This functionality effectively turns video generation from a passive viewing experience into an active, iterative creative process.
Hardware Requirements Remain Accessible
A significant technical milestone for the project is its optimization for standard computing hardware. The accelerated version of the model processes each video segment in eight steps, producing 720×1280 resolution footage at 24 frames per second. By utilizing quantization methods such as INT8 and FP8, along with system memory offloading, the model can operate on a single NVIDIA GeForce RTX 4090 graphics card. This accessibility significantly lowers the barrier for independent developers and researchers who wish to explore generative video without the need for massive server clusters.
Benchmarks Evaluate Control Accuracy
To ensure developers can measure the effectiveness of their implementations, Tencent has introduced the Hy-Nomas-Bench dataset. This resource includes 280 distinct test scenarios and 220 reference camera trajectories, specifically designed to stress-test the model’s ability to interpret complex text-to-video instructions. While the dataset provides a rigorous framework for evaluating interaction control, it does not include pre-generated videos or scoring metrics, leaving the benchmarking process to the community. The inclusion of lightweight LoRA adaptation further suggests that the system is intended for specialized domains, such as robotics or complex simulation environments, where precise spatial control is required.
The arrival of interactive, segment-based video generation marks a shift in how we might interact with AI-driven media. We would love to hear your thoughts on whether this level of granular control changes how you perceive the future of filmmaking; please share your comments with us below.
Your comment has been submitted,
it will be published after approval.